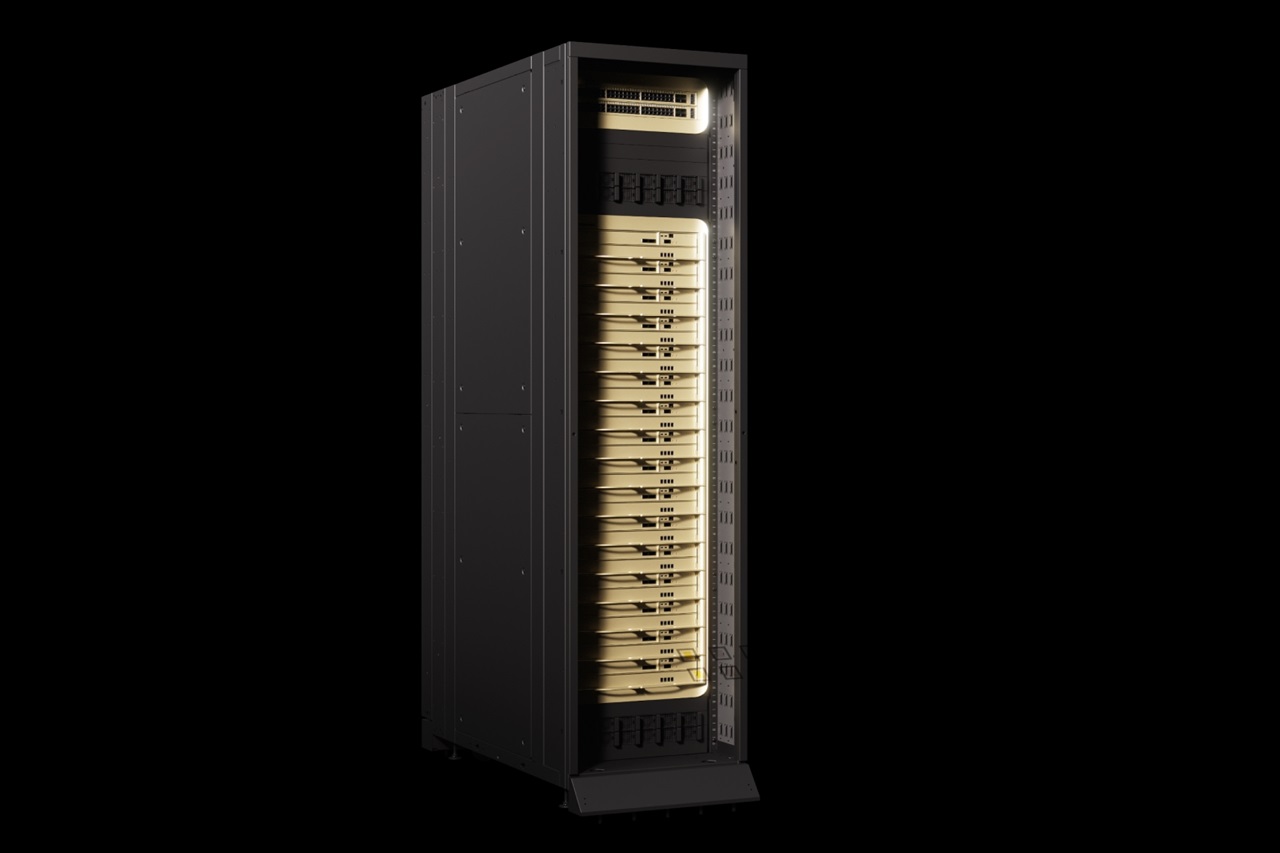
Nvidia’s Groq 3 LPX Inference Accelerator Moves Into Full Production for Faster Agentic AI
Nvidia has confirmed that the Groq 3 LPX inference accelerator has entered full production, marking an important step forward for faster, more responsive artificial intelligence systems. The platform is built to support the rapid growth of agentic AI, a new generation of AI tools designed to reason, plan, code, and complete complex tasks with greater independence.
As AI adoption expands across software development, automation, research, customer support, and enterprise workflows, demand for real-time inference performance continues to rise. The Groq 3 LPX accelerator is designed to address that demand by reducing latency and improving response times, helping AI applications deliver answers and actions more quickly.
Inference accelerators play a crucial role in modern AI systems. While training creates and improves AI models, inference is what happens when those models are used in real-world applications. Every chatbot response, code suggestion, reasoning step, or automated decision depends on inference performance. Faster inference can make AI tools feel more natural, efficient, and capable.
The move to full production suggests that the Groq 3 LPX platform is ready for wider deployment across AI infrastructure. This could benefit companies building agentic AI services that require fast decision-making, continuous task execution, and low-latency interaction. These workloads often need more than raw computing power; they require consistent speed, reliability, and efficiency at scale.
Agentic AI is becoming one of the most important areas in artificial intelligence. Unlike simple AI assistants that respond to one request at a time, agentic systems can break down goals, manage multi-step workflows, write and debug code, analyze data, and adapt based on results. For these systems to work smoothly, they need fast inference hardware capable of handling repeated model calls without slowing down the user experience.
By pushing the Groq 3 LPX inference accelerator into full production, Nvidia is positioning the platform as a solution for organizations preparing for the next wave of AI workloads. Lower latency can be especially valuable for AI coding assistants, autonomous research tools, enterprise automation platforms, and real-time reasoning systems.
The announcement also reflects the broader shift in the AI market from model training alone toward high-performance inference. As more businesses deploy AI products to millions of users, the ability to run models quickly and efficiently becomes just as important as building them. Hardware designed specifically for inference could help reduce bottlenecks and improve the performance of AI services used every day.
With full production now underway, the Groq 3 LPX accelerator may play a key role in expanding access to faster agentic AI. As real-time AI applications become more common, infrastructure that can deliver quick, reliable responses will be essential for the next generation of intelligent software.